Showing posts with label virtualization. Show all posts

Tuesday, December 15, 2015

Smaug - Application Data Protection for OpenStack


During the recent OpenStack Tokyo 2015 summit, we introduced a new project that we've been working on recently, which will provide an Application Data Protection as a Service (video) (slides).

What is Smaug?

Not to be confused with Application Security or DLP, Smaug deals with protecting the Data that comprises an OpenStack-deployed Application (what is referred to as "Project" in Keystone terminology) against loss/damage (e.g. backup, replication).
It does that by providing a standard framework of APIs and services that enables vendors to introduce various data protection services into a coherent and unified flow for the user.

We named it Smaug after the famous dragon from J.R.R. Tolkien’s “The Hobbit”, which was known to guard the treasures of the kingdom of Erebor, as well as have specific knowledge on every item in its hoard.  Unlike its namesake, our Smaug is designed to give a simple and user-friendly experience, and not burn a user to a crisp when they want to recover a protected item.

The main concept behind Smaug is to provide protection of an entire OpenStack project, across OpenStack sites (or with a single local site).

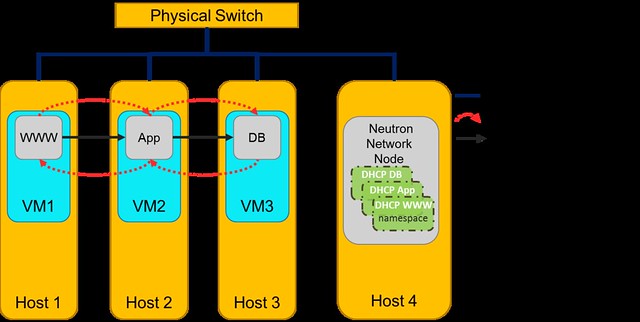
Lets take a typical 3-tier cloud app:


In order to fully protect such a deployment (e.g. Disaster Recovery), we would have to protect many resources, which have some dependency between them.

The following diagram shows how such a dependency tree might look:


In Smaug, we defined a plugin engine that loads a protection plugin for each resource type.
Then, we let the user create a Protection Plan, which consists of all the resources she wants to protect.
   
These resources can be divided into groups, each of which is handled by a different plugin in Smaug:
  • Volume - Typically, a block of data that is mapped/attached to the VM and used for reading/writing
  • VM - A deployed workload unit, usually comprised of some metadata (configuration, preferences) and connected resources (dependencies)
  • Virtual Network - The virtual network overlay where the VM runs
  • Project - A group of VMs and their shared resources (e.g. networks, volumes, images, etc.)
  • Image - A software distribution package that is used to launch a VM

Smaug Highlights 

Open Architecture

Vendors create plugins that implement Protection mechanisms for different OpenStack resources.

User perspective: Protect Application Deployment

Users configure and manage custom protection plans on the deployed resources (topology, VMs, volumes, images, …).
The user selects a "Protection Provider" from a selection of available Protection Providers, which is maintained and managed by the admin.

Admin perspective: Configure Protection Providers  

The Admin defines which Protection Providers are available to the users.  
A "Protection Provider" is basically a bundle of per-resource protection plugins and a bank, which are curated from the total available protection plugins and bank plugins.
In addition, the Admin configures a Bank Account for each user (tenant).


Smaug APIs

We are currently in the process of defining Smaug's set of User Service APIs:


Resource (Protectable) API

Enables the Smaug user to access information about which resource types are protectable (i.e. can be protected by Smaug).
In addition, enables the user to get  additional information on each resource type, such as a list of actual instances and their dependencies.

Plan API

Enables the Smaug user to create or edit Protection Plans using a selected Protection Provider, as well as access all the parameters of the plan.

Provider API 

Enables the Smaug user to list available providers and get parameters and result schema super-set for all plugins of a specific Provider.

Checkpoints API

Enables the Smaug user to access and manage Protection Checkpoints, as well as listing and querying of the existing Checkpoints in a Provider.In addition, provides Checkpoint Read Access to the Restore API, when recovering a protected application's data.
Calling the Checkpoint Create (POST) API will start a protection process that will create a Vault in the user's Bank Account, on the Bank that is assigned to the Provider.
The process will then pass the Vault on a call to the Protect action on each of the Protection Plugins assigned to the Provider, so each will write its metadata into the Vault. 
It is left up to the Plugin implementation to decide where to store the actual data (i.e. in the Vault or somewhere else).

Schedule Operation API

Enables the Smaug user to create a mapping between a Trigger and Operation(s) definitions . 

Smaug Architecture


We defined three services for Smaug:

Smaug API service

These top-level north-bound APIs expose Application Data Protection services to the Smaug user.
The purpose of the services is to maximize flexibility and accommodate for (hopefully) any kind of protection for any type of resource, whether it is a basic OpenStack resource (such as a VM, Volume, Image, etc.) or some ancillary resource within an application system that is not managed in OpenStack (such as a hardware device, an external database, etc.).

Smaug Schedule Service

This subsystem is responsible for scheduling and orchestrating the execution of Protection Plans.
The implementation can be replaced by any other external solution.
All actual Protection-related activities are managed via the Operation northbound APIs, in order to support:
  • Record maintaining of all operations in the Smaug database (to drive Operation Status APIs)
  • Decoupling the implementation of the Scheduler from the implementation of the Protection Service

Smaug Protection Service

This subsystem is responsible for handling the following tasks:
  • Operation Execution
  • protectable(resources) plugin management 
  • Protection provider management
  • Protection Plugin management
  • Bank Plugin management
  • Bank checkpoints sub-service

Join Smaug

We are currently in the process of reviewing the API definition
  • Our IRC (we are always there): #openstack-smaug 


Wednesday, October 14, 2015

Multi-Site Management in OpenStack

Managing multiple Openstack clouds as a single resource pool


In this series of posts, we would be diving into "Tricircle" 
- an open source project that promises to give a "single pane of glass" management over multiple OpenStack environments, using a cascading approach.

As more and more companies are deploying OpenStack, it is becoming clear that there is a need to be able to manage multiple cloud installations. The reasons range from application lifecycle management, through spill-over scenarios and all the way to multi-site Disaster Recovery orchestration.


So why would one care to deploy the same service over multiple environments?


There are multiple reasons, and here are a few:

  • Service continuity and geo-redundancy (in case of one site going awry)
  • Geo-based load balancing and service locality (in case traffic comes from various places in the globe, or if there are strict quality/latency requirements, or if there are regulatory constraints, etc)
  • Cost optimization (in case some resources are cheaper in another place)
  • Growth (in case one environment cannot grow enough)
  • Resource Utilization (in case you have multiple sites and want to aggregate their resources for better value or easier management)
  • Single Configuration (instead of continually synchronizing multiple sub-instances of the service)
  • ... (feel free to share additional incentives in the comments).

OpenStack Tricircle


Managing multiple OpenStack instances could be done in several ways, for example by introducing multi-site awareness into each project in OpenStack (which we ruled out due to complexity of evolving all OpenStack projects to do it).

The approach we took in Tricircle was to add a "Top" management OpenStack instance over multiple "Bottom" OpenStack instances.

The "Top" introduces a cascading service layer to delegate APIs downwards, and injects itself into several OpenStack components.


So, how does it feel to use such a "Top" OpenStack instance?


Well, first of all let's define the different users:
  1. The Multi-site Tenant Admin (the "User") - Uses the multi-site OpenStack cloud (create VMs, networks, etc.)
  2. The Multi-site Admin (the "Admin") - This user can add new sites, and needs to have the necessary credentials on them to put it together
User


For the "User", it is pretty straightforward: when you launch a VM, you get to choose from a list of Data Centers (a new drop box in Horizon), and then from a list of Availability Zones based on your Data Center selection, and that's basically it.

Admin


For the "Admin", you get a new "Add Site" API (in CLI only, at this point), and you need to have substantial knowledge about the "Bottom" sites you are adding (credentials and network-related information which we will cover in the next post).

Some High-Level Architecture


The "Top" Instance


The design principle we took was to reuse OpenStack components in the TOP and bottom layer as much as possible and to mange any OpenStack
deployment without any additional requirements (OpenStack API compatible).

For the top layer we used a non-modified OpenStack API layer to intercept operational requests and handle them in the cascading service.

Doing this required integrating with the different OpenStack core components:

Neutron 


  • We introduced a custom core plugin
  • Updates are written to the database 
  • Operational requests are forwarded to our OpenStack Adaptor service
  • Reads and Reports are served directly from the database

Nova


  • We implemented a custom Nova Scheduler that runs inside our OpenStack Adaptor service
  • We created a Compute Node emulation that runs in the Adaptor service and listens to the Nova Compute service queues
  • Our current working assumption is to map "Bottom" sites as "Compute Nodes" that reside on different logical AZs
  • The Compute Node emulation instance for each "Bottom" site also aggregates information and statistics that represent the site
  • At some point, we plan to let the admin decide how to expose the "Bottom" sites, e.g. different AZs on the "Bottom" site, or all the actual "Compute Nodes", etc. This will create a complete decoupling between the Adaptor and the "Cascading" service.

The "Bottom" Instances


We assume that the "Bottom" sites are unmodified and potentially heterogeneous (in terms of network, configuration and version).

At this stage, our design assumes a centralized Keystone service running on the "Top" (we are planing "Federated Keystone" in the future).

In order to add a "Bottom" site to the multi-site environment, the admin needs to deploy a "Cascaded" service, and register it in the "Top" site, using a special "add site" API.  Then, configure the "Bottom" site to use the "Top" Keystone.


The Full Picture


Here is how the entire system looks:


Is it really that simple?


From the user experience point of view - We hope it is.  
But in order to get it there, we needed to handle quite a few obstacles:
  • Resource Synchronization across the Multi-site
  • Cross-site network
  • Image synchronization
  • Metadata synchronization (e.g. flavors)
  • Resource Status monitoring and propagation (i.e. so that you can see what's happening from the "Top" dashboard) 

Coming next


In our coming posts, we will dive into resource synchronization, the cross-site networking, explain how we tackled the status and notification updates and share our approach to meeting large scale deployments.

Please share your thoughts about this in the comments.
We will be talking about this project in the upcoming OpenStack Tokyo summit, so if you're coming there, be sure to attend our talk.

To join the development effort: 

Tuesday, August 4, 2015

Centralized vs. Distributed SDN Control Path Paradigm

In a previous post I covered some misconceptions about SDN management and my view of the importance of the hybrid(proactive/reactive) model for scalability, and how we used this approach in the design of Dragonflow.

Today, i will discuss the two existing paradigms to SDN control path, and how it affects our road map in the Dragonflow project.

The first approach is the Centralized Controller.  Here, a controller (or a cluster of them) manages all the forwarding elements in the system, and retains a global view of the entire network. 

Most SDN controllers today run this way (ODL, ONOS, as well as Kilo version of Dragonflow).

The second approach is the Distributed Control Path.  Here, a local controller runs on each compute node and manages the forwarding element directly (and locally).  Thus, the control plane becomes distributed across the network.  

However, the virtual network topology needs to be synchronized across all the local controllers, and this is accomplished by using a distributed database.

Like everything else in life, there are advantages and disadvantages to each approach.  So, let's compare: 


Centralized Control Path


Pros


  • The controller has a global view of the network, and it can easily ensure that the network is in a consistent, optimal configuration
  • Simpler, agentless solution - Nothing needs to be installed on the compute nodes 
  • Any and all southbound APIs can be supported directly from the centralized controller (easier to integrate with legacy equipment)

Cons

  • Added latency in newly established flows, becomes a bottleneck in large scale deployments
  • Dependency on the controller cluster availability and scale
  • All advanced services are handled centrally, instead of locally, perpetuating a bottleneck as the scale grows
  • Large scale is usually controlled via BGP-based Confederations and multiple SDNC clusters which add more latency and complexity

Distributed Control Path


Pros

  • You can manage policies and introduce advanced services locally on each compute node, since you already have a local footprint
  • Significantly better scalability, now that you have the control plane completely distributed
  • Significantly better latency during reactive handling of PACKET_IN
  • Highly-available by design and no single-point-of-failure
  • Easier to integrate Smart NIC capabilities on local host level

Cons

  • Synchronization of the virtual network topology can be a challenge, as the amount of compute nodes increases
  • No global view
  • Extra compute is done on the local host
  • If you have heterogeneous forwarding elements (e.g. legacy switches), you need to have a centralized controller that connects them to the distributed control plane (which can complicate the management) 


What we chose and why


We decided earlier-on to go with a hybrid reactive/proactive model (against the widely-accepted proactive-only approach), as we saw that its advantages were overwhelming.  

The winning point of the reactive mode, as we see it, is that it improves the performance of the datapath, taking the performance toll instead on the control path of newly-established flows.  The main reason for that being a dramatic reduction of the number of flows that are installed into the forwarding element.

When combined with a pipeline that is deployed proactively, we could maximize the benefits of the reactive approach, while minimizing its cost.

However, like all solutions, at a certain scale it will break.


In very large deployments (e.g. a full datacenter), a central controller cluster becomes overwhelmed with the increase in volume of new connections.

A centralized controller made sense, while we were only handling new L3 connection path establishment (Dragonflow in Kilo).

However, when we came to add reactive L2 and other advanced services (like DHCP, LB, etc.), we realized that scaling the centralized controller cluster was becoming a huge challenge. 

A different approach must now be taken, and we believe this approach is to place a local controller on each compute node.  

Now that the control path bottleneck was mitigated, the problem moves to the logical data distribution between all the local controllers.

To mitigate that, we believe we can reuse the reactive approach, by letting the local controllers synchronize only the data they actually need (in lazy mode) use key/value distributed db engines that provide low latency. 

Sure, this will probably take some performance toll on the establishment of new flows, but we believe it will dramatically reduce the amount of data synchronization required, and therefore will take us to the next scalability level.


What we are doing in Dragonflow


We are currently working on introducing reactive L2 and L3 model into the local Draongflow controller.  

We are creating a pluggable distributed database mechanism to serve the logical data across the datacenter, which will enable the user to chose the best database to meet their specific needs and scale.

As always, we would love to have more people join the Dragonflow community and contribute to its success.

For additional information about the pluggable database layer, you can check out Gal Sagie's new blog post.

Tuesday, May 5, 2015

DragonFlow SDN based Distributed Virtual Router for OpenStack Neutron

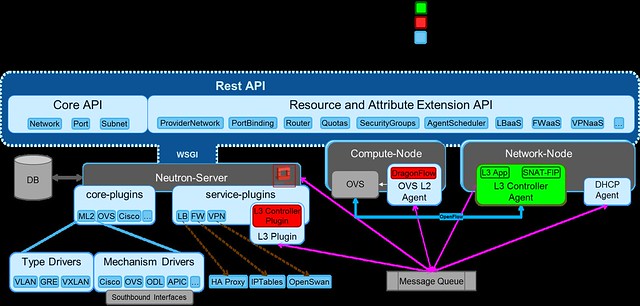
In my previous posts I presented a PoC implementation of an embedded L3 controller in Neutron that solves the network node bottleneck the SDN way, and overcomes some of the DVR limitations.
In this post I am going to cover the first release of DragonFlow - an SDN based Distributed Virtual Router L3 Service Plugin (aligned with OpenStack Kilo), now an official sub-project of Neutron.
The main purpose of DragonFlow is to simplify the management of the virtual router while improving performance, scale and eliminating single point of failure together with the network node bottleneck.
The DrangonFlow solution is based on separation of the routing control plane from the data plane. This is accomplished by implementing the routing logic in distributed forwarding rules on the virtual switches (called "flows" in OpenFlow terminology). To put this simply, the virtual router is implemented using OpenFlow flows only.
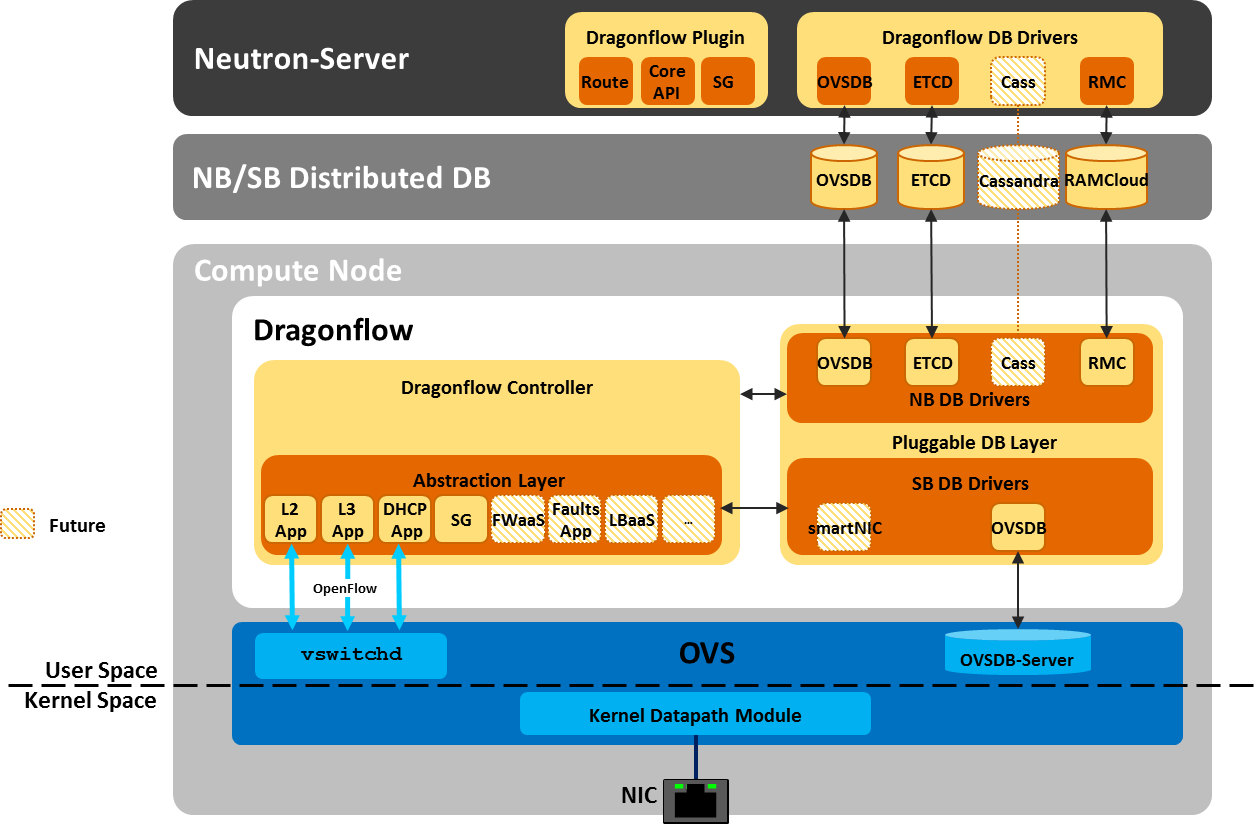
DragonFlow eliminates the use of software stack to act as a virtual router (the Linux network namespaces in the DVR and the legacy L3 architecture), it use purely OVS flow to act as a virtual router. A diagram showing DragonFlow components and overall architecture can be seen here:
DragonFlow High-level Architecture


DragonFlow Features for the Kilo Release:

  • East-West traffic is fully distributed using direct flows, reactively installed upon VM-to-VM first connection.
  • Support for all ML2 type drivers GRE/VXLAN/VLAN
  • Support for centralized shared public network (SNAT) based on the legacy L3 implementation
  • Support for centralized floating IP (DNAT) based on the legacy L3 implementation
  • Support for HA, in case the connection to the Controller is lost, fall back to the legacy L3 implementation until recovery. Reused all the legacy L3 HA. (Controller HA will be supported in the next release).


Key Advantages:

  • Performance improvements for inter-subnet network communication by removing the number of kernel layers (namespaces and their TCP stack overhead)
  • Scalability improvements for inter-subnet network communication by offloading L3 East-West routing from the Network Node to all Compute Nodes
  • Reliability improvements for inter-subnet network communication
  • Simplified virtual routing management, mange only active flows and not all possible 
  • Non Intrusive solution, does not rely on ML2 modification

How it works

  1. On bootstrap the L3 service plugin sends an RPC message to the L2 service plugin, setting the L3  Controller Agent as the controller of the integration bridge.
  2. The Controller queries the OVS  for its port configuration via Openflow, matches the actual ports configured on the OVS to the Neutron tenant networks data model. 
  3. Then, it installs the bootstrap flow pipeline that offloads all L2 traffic and local subnet L3 traffic into the NORMAL pipeline, while sending every unmatched VM-to-VM inter-sunbet traffic to the controller.
DragonFlow L3 Service Bootstrap

The following diagram shows the multi-table OpenFlow pipeline installed onto the OVS integration bridge (br-int) in order to represent the virtual router using flows:

bootstrap flows pipeline

The base table pipe-line is installed proactively on bootstrap while the East-West rules on the L3 Forwarding table are installed reactively on each first VM-to-VM communication.

If you would like to try it yourself, install guide is available here.
To join the development effort: 
My next post will cover the L3 reactive OpenFlow application, and how we install the East-West reactive flows. 

Thursday, January 15, 2015

Common Misconceptions about SDN Controller Management and Scalabilty

Here are a few common misconceptions about SDN controller management and scalability.

#1: Either Proactive mode or Reactive mode

When an SDN controller wants to enforce a set of rules or a policy on a forwarding element, it uses the southbound API, OVSDB, OpFlex, OpenFlow or others. In OpenFlow this process is called flow installation and it can be done using different methods: proactive, reactive or mixed (aka hybrid approach).  


Proactive

During bootstrap, the controller installs all flows and pipelines (multi-table entries) into all the forwarding elements.  The flows must cover all possible scenarios.
Whenever there is a change in the network, the controller removes or installs flows where necessary.


Reactive

When a packet arrives in a switch, a look-up is performed on the flow tables.
If there is no match and the switch is connected to a controller, it will forward the packet (either with or without its payload) to the controller.
In OpenFlow, this is called a PACKET_IN message.

It is also possible to create rules that forward the packet to the controller when matched and we call that...


Mixed Proactive / Reactive

With the mixed approach, you can benefit from the best of both worlds, achieving a balance between dynamic management and performance.

For frequently-used and rarely-modified flows, you install a pipeline and flows proactively.

For unmatched flows, or for flows that you want to handle in-line in your SDN application, you install a flow to forward the packet to the controller.

This mixed approach allows the controller to focus on making real-time dynamic decisions only on the traffic that requires it (reactive), while leaving the heavy-lifting of the majority of the traffic to the real-time forwarding element (proactive).

In addition, with this approach you can avoid over-provisioning the forwarding element with flows that are rare, thus dramatically reducing the number of entries in the flow tables. 

#2: Lack of Scalability and High Availability


In SDN, the control plane (i.e. the SDN Controller) is separated from the data plane (i.e. the Forwarding Elements).

Due to the centralized nature of control in SDN, we now need to support high availability and redundancy of the Control Plane.

In OpenFlow, the Forwarding Element (the Switch) connects to the controller via TCP or via TLS for secure channels.

Up until OpenFlow v1.2, whenever the connection to the controller was lost, the switch would lose the ability to forward PACKET_IN messages to the controller, thus having to drop all unmatched traffic or handle it in the NORMAL switch (only in switches that implemented the dual nature). 

This non-deterministic approach would yield unpredictable network behavior 
while the controller was unavailable.

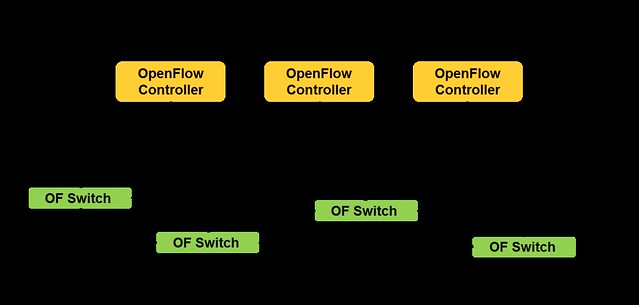
OpenFlow v1.2 introduced the capability of working with multiple controllers.
The Master and Slave modes provide a mechanism for Active-Passive high availability, whereas the Equal mode provides an Active-Active model.

OpenFlow multiple controllers


With the multi-controller capability, we gained the control plane high availability we needed, improved reliability, fast recovery from failure and controller load balancing.

#3: You cannot design SDN Applications for Really Big Scale


Utilizing the two mechanisms I covered - Mixed-Mode and Multi-Controller - is the key to designing really big scale SDN applications.

If you take care to design your application to be stateless (whenever possible) and share nothing (or little) with other controller instances you can benefit from the Reactive mode where any instance can handle any flow.

In my opinion, the best approach for achieving minimal controller response latency and maximal bandwidth while keeping the dynamic allocation of flows, is by using all of these mechanisms together.

When you add to that the OVS OpenFlow extensions and the dual-nature Hybrid OpenFlow capability (which I covered in my previous post), you can really gain a dramatic performance and management boost.


In my next post I will demonstrate how we utilized these design guidelines and capabilities in a prototype for an alternative to Neutron's L3 Distributed Virtual Router.

Thursday, January 8, 2015

Openstack Neutron DVR - Summary

Following my 3-post series about Openstack Juno DVR in detail, this post is a summary of DVR, in my point of view.

In the next post I’m going to present a POC implementation of an embedded L3 controller in Neutron that solves the problem differently. In this post I’d like to explain the motivation for yet another L3 implementation in Neutron.

I believe the L3 Agent drawbacks are pretty clear (centralized bottleneck, limited HA, etc), so in this post I’m going to cover the key benefits and drawbacks of DVR as I see them. So without further ado, let’s start.

Pros


First of all, from a functional point of view, DVR successfully distributed the East-West traffic and the DNAT floating IP, which provided significant offload from the Network node contention. This achieved two key benefits, first is that the failure domains are much smaller (Network node failure only affects SNAT) and the second is scalability due to the distribution of the load on all the compute nodes. 


Cons

The approach for DVR’s design was to take the existing centralized router implementation based on Linux network namespaces and clone it on all compute nodes. This is an evolutionary approach and an obvious step to take in distributing L3 from which we’ve learned a lot from. However, it adds load and complexity in three major areas: Management, Performance and Code.

To explain the technical details I will briefly cover two Linux networking constructs used in the solution for East-West communications:

1. Linux network namespaces (which internally load a complete TCP/IP stack with ARP tables and routing tables)
2. OVS flows

OVS flows were needed in order to block the local ARP, redirect return traffic directly to the VMs and to replace the router ports MAC (which cannot be accomplished reasonably using namespaces alone). On the flip side, OVS flows can easily accomplish everything that DVR uses the namespaces for (in East-West communications) and perhaps more importantly it does so in a more efficient way (avoids the overhead of the extra TCP/IP stack etc). To hint at our solution, flows also allow us to further improve the solution by selectively using a reactive approach where relevant.


Extra Flows Install for DVR
So overall it seems that using the Linux network namespace as a black box to emulate a router is an overkill. This approach makes sense in the centralized solution (L3 Agent) where for each tenant’s virtual router we use a single namespace in the DC, however, in the distributed approach where the number of namespaces in the DC is multiplied by the number of compute nodes this needs to be reevaluated.
If you’re not convinced yet, here is a summary of the implications of using this approach:

Resource consumption and Performance

1. DVR adds an additional namespace as well as virtual ports per router on all compute nodes that host routed VMs. This means additional TCP/IP stacks that each and every cross subnet packet traverses. This adds latency and host CPU consumption.

2. ARP tables on all namespaces in the Compute nodes are proactively pre-populated with all the possible entries. Whenever a VM is started, all compute nodes which have running VMs from the same tenant will be updated to keep these tables up to date (which potentially adds latency to VM start time)

3. Flows and routing rules are proactively installed on all compute nodes.

Management complexity

1. Multiple configuration points that need to be synchronized: namespaces, routing tables, flow tables, ARP tables and IPTables.

2. Namespaces on all compute nodes need to be kept in sync all the time with the tenant’s VM ARP tables and routing information and need to be tracked to handle failures etc.

3. The current DVR implementation does not support a reactive mode (i.e. creating a flow just-in-time), thus all possible flows are created on all hosts, even If they’re never used.

Code Complexity

1. The DVR required cross-component changes due to its multi configuration points: The Neutron server Data Model, ML2 Plugin, L3 Plugin , OVS L2 Agent and the L3 Agent.

2. Using all Linux networking constructs in a single solution (namespaces, flows, linux bridges, etc) requiring code that can manage all of it.

3. The solution is tightly coupled with the overlay manager (ML2) which means that the addition of every new type driver (today only vxlan) requires code additions on all levels (as can be seen by the vlan patches)

In my next post I will present an alternative solution, we evaluated and developed (code available) for distributing the virtual router that attempts to overcome these limitations, using SDN technologies.

Comments, questions and corrections are welcome.